
As an Apache Pinot cluster grows from a handful of servers to dozens or hundreds, routine operations such as version upgrades and server maintenance start to require more planning.
Restarting servers one at a time is a safe approach, but on a sufficiently large cluster it can turn a routine upgrade into a maintenance operation that lasts many hours — or even days.
Restarting larger batches is faster, but only if you know that taking those servers offline won’t remove every available replica of a segment.
This is one of the problems Pinot’s instance assignment, replica groups, and pool-based placement are designed to solve.
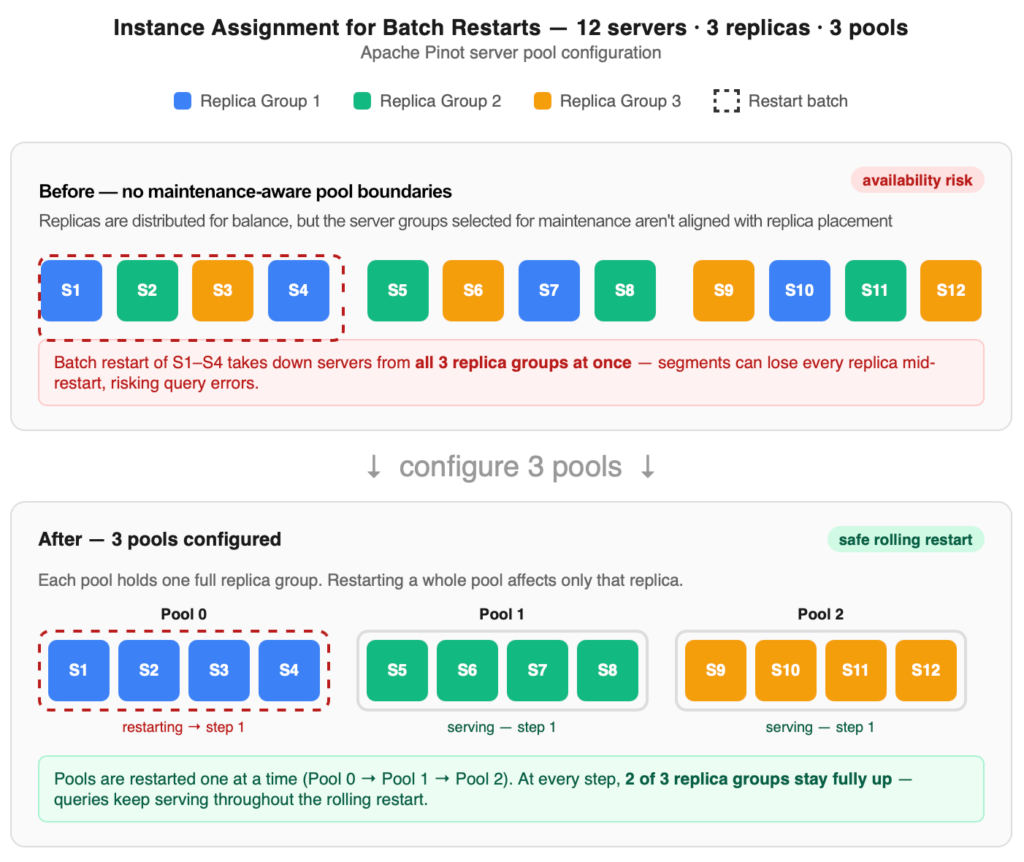
By organizing servers into explicit pools and distributing replica groups across those pools, you can create predictable maintenance boundaries. Instead of restarting arbitrary servers and hoping replica placement works in your favor, you can take servers from one pool offline while replicas in other pools continue serving queries.
At StarTree, this is a pattern we use extensively when operating larger Pinot deployments. In this post, we’ll look at how it works, how to configure it, and some of the operational details that matter once you’re running it in production.
Why large clusters change the restart problem
Pinot’s default instance-assignment strategy is intentionally simple: servers are shared across tables and Pinot uses balanced segment assignment to distribute data.
That’s a good default, particularly for smaller clusters. Apache Pinot’s own documentation describes it as working well when you have relatively few tables and resources can be shared across the cluster.
At a larger scale, however, maintenance introduces another requirement: you need control over which replicas can disappear together.
Imagine a cluster with 30 servers and a table with three replicas.
If you select five arbitrary servers for a batch restart, those servers may contain replicas belonging to several different replica groups. Depending on their placement, you could substantially reduce redundancy for some segments while the servers are unavailable.
Even if every segment retains an available copy, concentrating query traffic onto fewer servers can create hot spots and cause latency to increase.
You could avoid that risk by restarting every server individually. But as clusters get larger, and as server startup involves loading more segments, indexes, or upsert state, that quickly becomes slow.
What we want instead is a maintenance boundary that maps cleanly onto Pinot’s replica placement.
That’s where pools come in.
Using pools as maintenance boundaries
A pool is a logical grouping of Pinot server instances.
You can align pools with boundaries that make sense for your infrastructure, such as:
- availability zones or racks;
- groups of Kubernetes nodes;
- groups of servers you intend to upgrade together.
The important part isn’t simply grouping the machines. The value comes from combining pools with replica-group-based instance assignment.
With pool-based assignment enabled, Pinot can place replica groups onto different pools. Servers within a pool then form a predictable failure or maintenance domain rather than an arbitrary collection of nodes.
Apache Pinot explicitly describes pool-based instance assignment as a strategy for accelerating no-downtime rolling restarts in large shared clusters.
For a three-replica deployment, the conceptual layout looks something like this:
Apache Pinot cluster

Pool 0  ─────> Replica Group 0

Pool 1  ─────> Replica Group 1

Pool 2  ─────> Replica Group 2
Each replica group contains a complete copy of the table’s segments. That means servers belonging to one pool can be taken out of service while copies remain available from the other replica groups.
Configuring pool-based instance assignment
There are two parts to the configuration:
- assign Pinot server instances to pools;
- configure tables to use pool-based, replica-group instance assignment.
1. Assign servers to pools
Pool membership is stored in the server’s Helix InstanceConfig.
A simplified example might look like:
{
  "id": "Server_10.0.0.1_8098",
  "mapFields": {
    "pool": {
      "DefaultTenant_OFFLINE": "0",
      "DefaultTenant_REALTIME": "0"
    }
  }
}Code language: JSON / JSON with Comments (json)
Another set of servers might belong to Pool 1, another to Pool 2, and so on.
How you divide the servers depends on what you’re trying to protect against. For planned maintenance, you may simply want roughly equal-sized restart groups. If you’re using the same layout for infrastructure resilience, aligning pools with availability zones or other fault domains can be useful as well.
2. Configure instance assignment for the table
Next, configure the table’s instanceAssignmentConfigMap.
For an offline table, a simplified example looks like this:
{
  "tableName": "my_high_throughput_table_OFFLINE",
  "tableType": "OFFLINE",

  "segmentsConfig": {
    "replication": "3"
  },

  "instanceAssignmentConfigMap": {
    "OFFLINE": {
      "tagPoolConfig": {
        "tag": "DefaultTenant_OFFLINE",
        "poolBased": true
      },

      "replicaGroupPartitionConfig": {
        "replicaGroupBased": true,
        "numReplicaGroups": 3
      }
    }
  }
}
Code language: JSON / JSON with Comments (json)
The key ideas here are:
poolBased:true tells Pinot to take the configured server pools into account.replicaGroupBased: trueenables replica-group assignment.numReplicaGroups: 3creates three independent replica groups for this example.
Current Apache Pinot documentation uses replicaGroupPartitionConfig for this part of the configuration.
Treat the example above as a starting point rather than something to copy blindly into production. Instance assignment has additional controls for selecting instances, partitioning data, minimizing movement, and handling different table types.
In particular, real-time tables distinguish between CONSUMING and COMPLETED instance assignments in addition to OFFLINE assignment. Pinot can use the same assignment for consuming and completed segments, or you can configure them separately.
For the exact configuration supported by your Pinot version, refer to the official documentation. Apache Pinot Instance Assignment documentation
What if you already have a running cluster?
Most people reading this probably aren’t designing a Pinot cluster from scratch.
You may already have hundreds of tables and a large amount of data distributed across your existing servers.
Fortunately, changing instance assignment doesn’t require rebuilding the cluster.
At a high level, the migration is:
- Define the pool layout you want.
- Add the corresponding pool configuration to your servers.
- Update the
InstanceAssignmentConfigfor each table. - Rebalance the table so Pinot moves segments into the new assignment.
- Verify the resulting instance and replica placement.
- Only then start using pools as restart boundaries.
Pinot’s documentation explicitly supports changing instance assignment by updating the table configuration and running a table rebalance; Pinot can then reassign servers and move the segments into the new layout.
For a large existing deployment, this migration deserves the same care as any other significant data movement operation. Don’t change hundreds of tables at once because the end state looks good on paper. Roll the pattern out incrementally, observe movement and capacity, and verify the resulting assignments before expanding it.
A safer batch-restart workflow
Once your tables are correctly aligned with pools, the restart procedure becomes much more deterministic.
Instead of selecting arbitrary servers across the cluster, operate within one pool at a time.
Step 1: Check cluster health
Before taking anything offline, establish that the cluster is healthy.
At a minimum, verify:
- instances and segments are in their expected states;
- replica placement is correct;
- ingestion is healthy for real-time workloads;
- CPU and memory have sufficient headroom;
- query error rates and latency are normal; and
- the remaining pools have enough capacity to carry additional traffic.
The last point is easy to underestimate.
If you have three equal-sized pools and temporarily remove one, the remaining two pools will each carry more traffic. In a perfectly balanced system, the surviving capacity is now handling roughly 150% of its usual per-pool load.
Pool-based placement protects availability of replicas. It doesn’t manufacture additional CPU or memory capacity.
Step 2: Restart servers within Pool 0
You can now begin restarting servers from the first pool.
Because other replica groups remain available in Pools 1 and 2, brokers can continue routing queries to available copies of the segments.
How aggressively you parallelize within the pool should depend on your workload.
The fact that your architecture allows an entire pool to become unavailable doesn’t necessarily mean restarting every server in that pool simultaneously is the best operational choice.
Factors such as:
- spare query capacity;
- number and size of segments per server;
- startup time;
- cache warming;
- real-time ingestion;
- upsert metadata; and
- pressure on deep storage
can all affect the appropriate batch size.
In StarTree, for example, our pool-aware restart automation has used batches of servers within the safe pool boundary rather than treating “one pool” as synonymous with “restart everything simultaneously.” StarTree’s release notes describe an optimization that restarts servers in batches of five when the relevant pool and replica-group conditions are met.
The important idea is that pools give your automation a safe boundary within which it can parallelize.
Step 3: Wait for the pool to converge
Don’t treat “the process has restarted” as equivalent to “the server is ready.”
Before moving to the next batch or pool, verify that:
- the instances are back online;
- their assigned segments are loaded;
- Helix state has converged;
- real-time ingestion has recovered;
- latency and error rates have returned to expected levels; and
- any important caches or indexes have recovered sufficiently for production traffic.
The original implementation of this pattern at StarTree explicitly checks health and Helix Ideal State / External View convergence before progressing.
This step is especially important for large servers or workloads where restarting involves reconstructing significant in-memory state.
Step 4: Continue through the remaining pools
Once Pool 0 is healthy again, continue to Pool 1.
Then Pool 2.
At every point, keep at least one healthy replica available and make progress conditional on the previous group successfully returning to service.
This turns the restart process from “restart nodes and watch what happens” into a sequence of explicit, observable state transitions.
Production considerations
The basic idea is straightforward. The operational details determine how well it works in practice.
Leave capacity headroom
If a maintenance operation removes one-third of your serving capacity, the other two-thirds need to handle the workload.
Test that assumption before the maintenance window rather than discovering your capacity limit during it.
For high-concurrency workloads, p95 and p99 query latency can be more useful signals than average CPU utilization alone.
Be conservative with the first batch
Even when your placement is correct, start with a smaller batch.
Measure:
- server recovery time;
- segment loading time;
- query latency;
- error rate;
- ingestion lag; and
- pressure on your object store or deep store.
You can increase parallelism once you know how the cluster behaves.
Account for real-time and upsert workloads
Not every Pinot server has the same restart characteristics.
Real-time tables may need to recover consuming state, while upsert workloads can have substantial primary-key metadata to restore.
This can materially affect how long a server takes to become useful after restarting.
StarTree has invested heavily in this area as part of operating large upsert deployments; newer StarTree releases, for example, include improvements for reusing persisted upsert metadata to reduce restart times.
Automate the health gates, not just the restart
It’s relatively easy to write automation to restart a batch, delay, then restart the next batch. That’s not the automation you want.
A production restart controller should be driven by state, not arbitrary timers:
- restart batch
- wait for instances
- wait for segment assignment
- wait for ingestion
- validate query health
- continue
Kubernetes StatefulSets, operators, Ansible, or your own orchestration can all implement this pattern.
The important thing is to make “healthy enough to continue” explicit.
What we’ve learned operating Pinot at StarTree scale
At StarTree, pool-based instance assignment has become an important part of how we operate medium and large Pinot clusters across both SaaS and BYOC deployments.
The reason isn’t that Pinot requires this level of configuration for normal operation.
It’s that once you’re operating a lot of Pinot infrastructure, predictability matters.
You want your automation to know:
- which servers can safely disappear together;
- where the surviving replicas are;
- whether sufficient capacity remains;
- when restarted servers are actually healthy; and
- whether it’s safe to proceed to the next group.
For our largest environments, structuring clusters this way has reduced upgrade operations that previously took days down to hours.
We also use server pools as part of our availability-zone strategy. Aligning placement with infrastructure fault domains means the same concepts that make planned upgrades safer can also improve resilience when infrastructure fails unexpectedly.
That operational experience is also one of the advantages of running Pinot through StarTree Cloud.
The Pinot primitives, instance assignment, replica groups, pools, rebalancing, health checking, are all powerful tools you can use yourself. StarTree builds the automation, guardrails, monitoring, and operational workflows around those primitives so that upgrades and other routine cluster operations don’t have to become projects of their own.